AI Workflow Automation Failures: Plan Retries, Approvals and Human Recovery
Define what automation should retry, pause or hand to a person before connecting AI workflows to business systems.
In this article
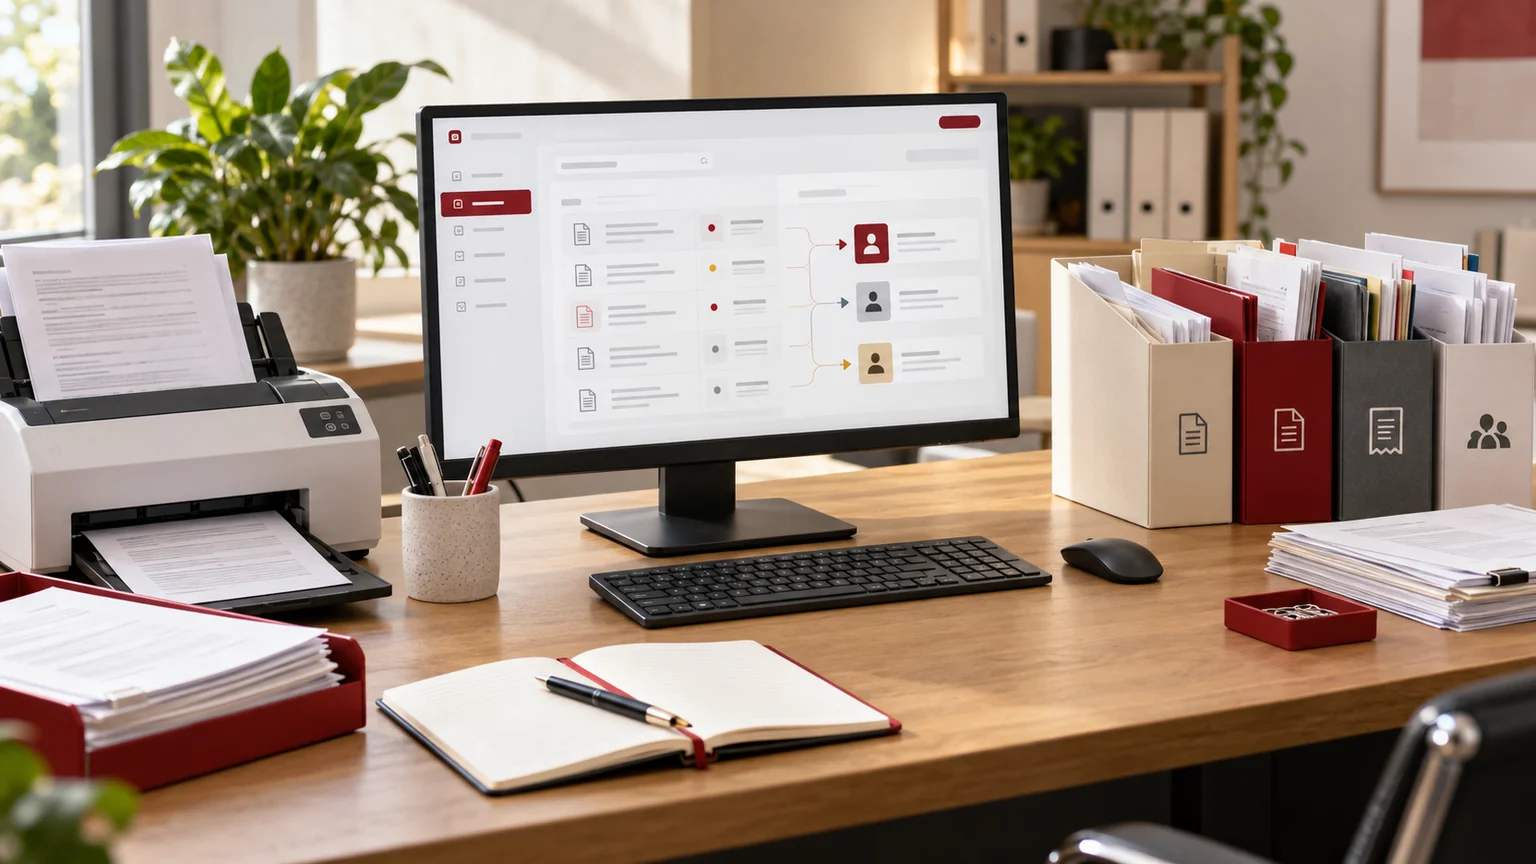
Editorial illustration. Any screens and records are illustrative, not a delivered client system.
An AI workflow is not production-ready simply because the happy path completes. A connection can time out, an approval can expire or a downstream system can accept an action before the workflow receives confirmation. Blindly trying again can create duplicate work or an unintended external action.
I scope AI workflow automation error handling alongside the business process. The useful deliverable is a recovery plan with observable states and named owners. It should explain which failures are safe to retry, which require approval and when a person must decide what happens next.
Map actions and side effects before retries
List each step from input to final action. Separate reading information from changing it, sending a message or committing an external operation. An unanswered read request and an uncertain payment or outbound message do not have the same recovery implications.
Give each operation a business meaning and an identifier where the integration supports one. Ask what happens if the same step runs twice. This is particularly important when a workflow contains both AI interpretation and deterministic system actions. Re-running an interpretation should not quietly repeat every action that followed the original result.
Use explicit error handling rather than endless attempts
AWS Step Functions error-handling guidance illustrates defined retry and catch behaviour. That is an implementation pattern, not a requirement to choose AWS. Your chosen system still needs a policy for recognised failures and a stopping point.
Distinguish a temporary service interruption from invalid input, missing permission or a business rejection. Retrying the same invalid data does not correct it. Record the allowed attempt limit, delay and escalation owner. Keep a visible final state when recovery is exhausted so staff can act rather than assuming the workflow is still making progress.
Write a recovery matrix before building the interface
This fictional planning matrix illustrates a custom automation brief. Its actions must be adapted to the real systems and business permissions.
| Failure class | Automatic response | Approval boundary | Human recovery |
|---|---|---|---|
| Temporary read failure | Bounded safe retry | No new external action | Inspect if exhausted |
| Invalid input | Stop and explain | Do not invent missing values | Correct source data |
| Uncertain write result | Check operation status | Do not blindly replay | Confirm prior outcome |
| Expired approval | Pause operation | Require valid approval | Review current request |
| Permission denied | Stop affected action | Do not broaden access | Administrator review |
Add the operation identifier, evidence retained and person who can resume. A red error badge is not a recovery procedure.
Make retry safety a per-operation decision
Google Cloud Workflows retry guidance distinguishes retry policies, including whether operations are idempotent. A repeated operation needs to avoid an additional unintended side effect; a generic “retry on failure” setting cannot establish that property by itself.
Check the downstream API and the business action. Some systems support request identifiers or status lookups; others leave uncertainty after a timeout. Define the recovery route for the actual integration. Do not claim exactly-once execution simply because the workflow stores an attempt count. Staff may need to reconcile the external result before any replay is allowed.
Keep approval tied to the action being approved
An approval should identify what will happen, to which record or recipient, and with which important values. If those values change after approval, decide whether the action needs review again. A general approval from earlier in the workflow should not authorise any later output by default.
Define who can approve, how long a decision remains valid and what happens when the approver is unavailable. Make rejection and expiry real states. Do not let the AI reinterpret an approval as permission to broaden scope. Human review is a control that needs clear evidence and permissions; its presence alone is not a guarantee that mistakes cannot occur.
Provide an operator view that supports a decision
The person recovering a workflow needs the affected business record, last confirmed step, observed failure and allowed next actions. Show whether an external action may already have happened. Keep secrets and unnecessary personal information out of diagnostic messages.
Offer only recovery actions that match the operation’s state. “Retry all” is dangerous when earlier steps include outbound messages or record creation. Record who resumed or cancelled the workflow and why. If an administrator changes configuration to restore service, that should not erase the original failure evidence or silently restart every paused task.
Test failures in a bounded pilot
A pilot should deliver the workflow map, recovery matrix, permission boundaries, operator instructions and a test record. Use controlled destinations and fictional business records. Agree which external actions are disabled or simulated during testing.
- A temporary safe read fails and recovers within the agreed bounds.
- Invalid input stops with a useful correction route.
- An uncertain external write is not blindly duplicated.
- Rejected or expired approval prevents the dependent action.
- An authorised operator can investigate and take the permitted next step.
- Repeated recovery attempts leave an understandable history.
What to include in your automation brief
Share one workflow, its systems, authorised actions and current manual recovery process. Identify the actions that would be costly or confusing if repeated. Include who can approve, who operates the workflow and which evidence staff need to resolve uncertainty. Do not send credentials in the brief.
My agentic AI pilot guide covers bounded agent tasks, while the small-business automation guide helps choose the initial workflow. I can scope custom automation implementation with explicit failure behaviour and human recovery, so the pilot tests more than a successful demonstration.
Written by
Jagjeet Singh
Full stack development, WordPress engineering and practical web products. I work with businesses, teams and agencies in India and worldwide.
Explore my work

